Fisch

joined 2 years ago
[–] Fisch@discuss.tchncs.de 1 points 1 day ago* (last edited 1 day ago)

I'm a little late here but I can explain it.

What Sonarr, Radarr and the others do automatically is scan an RSS feed of new releases. Basically, they look through the things that were uploaded to each tracker, since the last scan, to see if anything should be downloaded. The issue with this is that this only finds the things that were uploaded since the media item (show or movie) was added, not things that were uploaded before then. What this software does (and Huntarr used to do) is run a full search on the indexers, so the *arr apps can find any file that has ever been uploaded to the trackers. It's the same search you can trigger manually.

Technically, adding a media item, manually triggering a full search once and then relying on the automatic RSS scan should give you the same result (unless any trackers were down while you ran the manual search, which is one of the issues with this approach) but, for example, I use Seerr, so friends and family can add new stuff to my *arr apps but Seerr doesn't trigger a full search when something gets added, so I would have to manually trigger the full search once every time someone adds something. The point of having something like Fetcharr is that the full search gets triggered automatically. In addition, it does so periodically instead of just once, so that fixes issues like trackers being down when the search was triggered or a download not being found in the RSS feed despite it existing (not sure if the second one ever happens but it technically could and this would solve that issue).

Edit: I also just saw that the GitHub page for this has an explanation as well:

I learned that at *arr stack uses RSS feeds to scan for and fetch updates, so if your indexer doesn't support those feeds or the feeds or too old (or a myriad of other issues that can come from this kind of system) then you won't get replacement content even if it exists. This is why these kinds of "hunting", "fetching", "upgrading", etc systems work so well. They simply force the *arr apps to periodically update their content through their configured indexer, regardless of RSS feed availability.

[–] Fisch@discuss.tchncs.de 23 points 5 days ago (1 children)

Probably just because it's from Instagram, I searched for it on TikTok first and that post put a black box over it 😭

[–] Fisch@discuss.tchncs.de 107 points 5 days ago (12 children)

Republican news outlets seem to be reporting a lot on him (Apparently it's Fox News' new favorite topic, getting even more coverage than trans people) and this is what the post is referencing:

[–] Fisch@discuss.tchncs.de 39 points 2 weeks ago (1 children)

This kinda feels like trolling tbh, like, shooting cops in a GTA game isn't new

[–] Fisch@discuss.tchncs.de 4 points 2 weeks ago

And a lot of clients can automatically mark posts as read when you scroll past them. That's how I configured it and it works really well for me.

[–] Fisch@discuss.tchncs.de 4 points 3 weeks ago

Everything you can find on the internet is a "random URL" in that sense but that URL can be searched on search engines and shared. But I don't know how that p2p git thing works, so maybe I'm assuming it's more complicated than it actually is.

[–] Fisch@discuss.tchncs.de 3 points 3 weeks ago (2 children)

I don't really see what that solves tbh. Not having a central source of truth seems like it could cause issues and git is already pretty much decentralized because everyone who's working on a repo will have a copy on their own device and cam upload that to whatever forge they want. Aside from that, you lose all the features a git forge gives you, especially the ability for people to actually find the repo.

[–] Fisch@discuss.tchncs.de 18 points 3 weeks ago (4 children)

There are already alternatives to GitHub and I think Forgejo is still working on federation. The most active Yuzu fork (as far as I'm aware) is Eden and that has its own Forgejo instance.

[–] Fisch@discuss.tchncs.de 2 points 3 months ago

Ja natürlich, die erste vape die ich geraucht hab war auch illegal und mit 50mg/ml, aber mich hat einfach überrascht, dass es scheinbar Länder gibt in denen so ein hoher Wert sogar legal ist

[–] Fisch@discuss.tchncs.de 3 points 3 months ago (2 children)

Germany only allows 20mg/ml, I didn't know there were countries that allowed 60??? 😭


cross-posted from: https://discuss.tchncs.de/post/21001865

I just installed Piped using podman-compose but when open up the frontend in my browser, the trending page is just showing the loading icon. The logs aren't really helping, the only error is in piped-backend:

java.net.SocketTimeoutException: timeout
	at okhttp3.internal.http2.Http2Stream$StreamTimeout.newTimeoutException(Http2Stream.kt:675)
	at okhttp3.internal.http2.Http2Stream$StreamTimeout.exitAndThrowIfTimedOut(Http2Stream.kt:684)
	at okhttp3.internal.http2.Http2Stream.takeHeaders(Http2Stream.kt:143)
	at okhttp3.internal.http2.Http2ExchangeCodec.readResponseHeaders(Http2ExchangeCodec.kt:97)
	at okhttp3.internal.connection.Exchange.readResponseHeaders(Exchange.kt:110)
	at okhttp3.internal.http.CallServerInterceptor.intercept(CallServerInterceptor.kt:93)
	at okhttp3.internal.http.RealInterceptorChain.proceed(RealInterceptorChain.kt:109)
	at okhttp3.internal.connection.ConnectInterceptor.intercept(ConnectInterceptor.kt:34)
	at okhttp3.internal.http.RealInterceptorChain.proceed(RealInterceptorChain.kt:109)
	at okhttp3.internal.cache.CacheInterceptor.intercept(CacheInterceptor.kt:95)
	at okhttp3.internal.http.RealInterceptorChain.proceed(RealInterceptorChain.kt:109)
	at okhttp3.internal.http.BridgeInterceptor.intercept(BridgeInterceptor.kt:83)
	at okhttp3.internal.http.RealInterceptorChain.proceed(RealInterceptorChain.kt:109)
	at okhttp3.internal.http.RetryAndFollowUpInterceptor.intercept(RetryAndFollowUpInterceptor.kt:76)
	at okhttp3.internal.http.RealInterceptorChain.proceed(RealInterceptorChain.kt:109)
	at okhttp3.internal.connection.RealCall.getResponseWithInterceptorChain$okhttp(RealCall.kt:201)
	at okhttp3.internal.connection.RealCall.execute(RealCall.kt:154)
	at me.kavin.piped.utils.RequestUtils.getJsonNode(RequestUtils.java:34)
	at me.kavin.piped.utils.matrix.SyncRunner.run(SyncRunner.java:97)
	at java.base/java.lang.VirtualThread.run(VirtualThread.java:329)

Would appreciate it if anyone could help me. I also wasn't sure what info to include, so please ask if there's any more info you need.
72
submitted 2 years ago* (last edited 2 years ago) by Fisch@discuss.tchncs.de to c/selfhosted@lemmy.world
 

All the public Piped instances are getting blocked by YouTube but do small selfhosted instances, that are only used by a handful of users or just yourself, still working? Thinking of just selfhosting it.

On a side note, if I do it, I'd also like to install the new EFY redesign or is that branch too far behind?

Edit: As you can see in the replies, private instances still work. I also found the instructions for running the new EFY redesign here

0
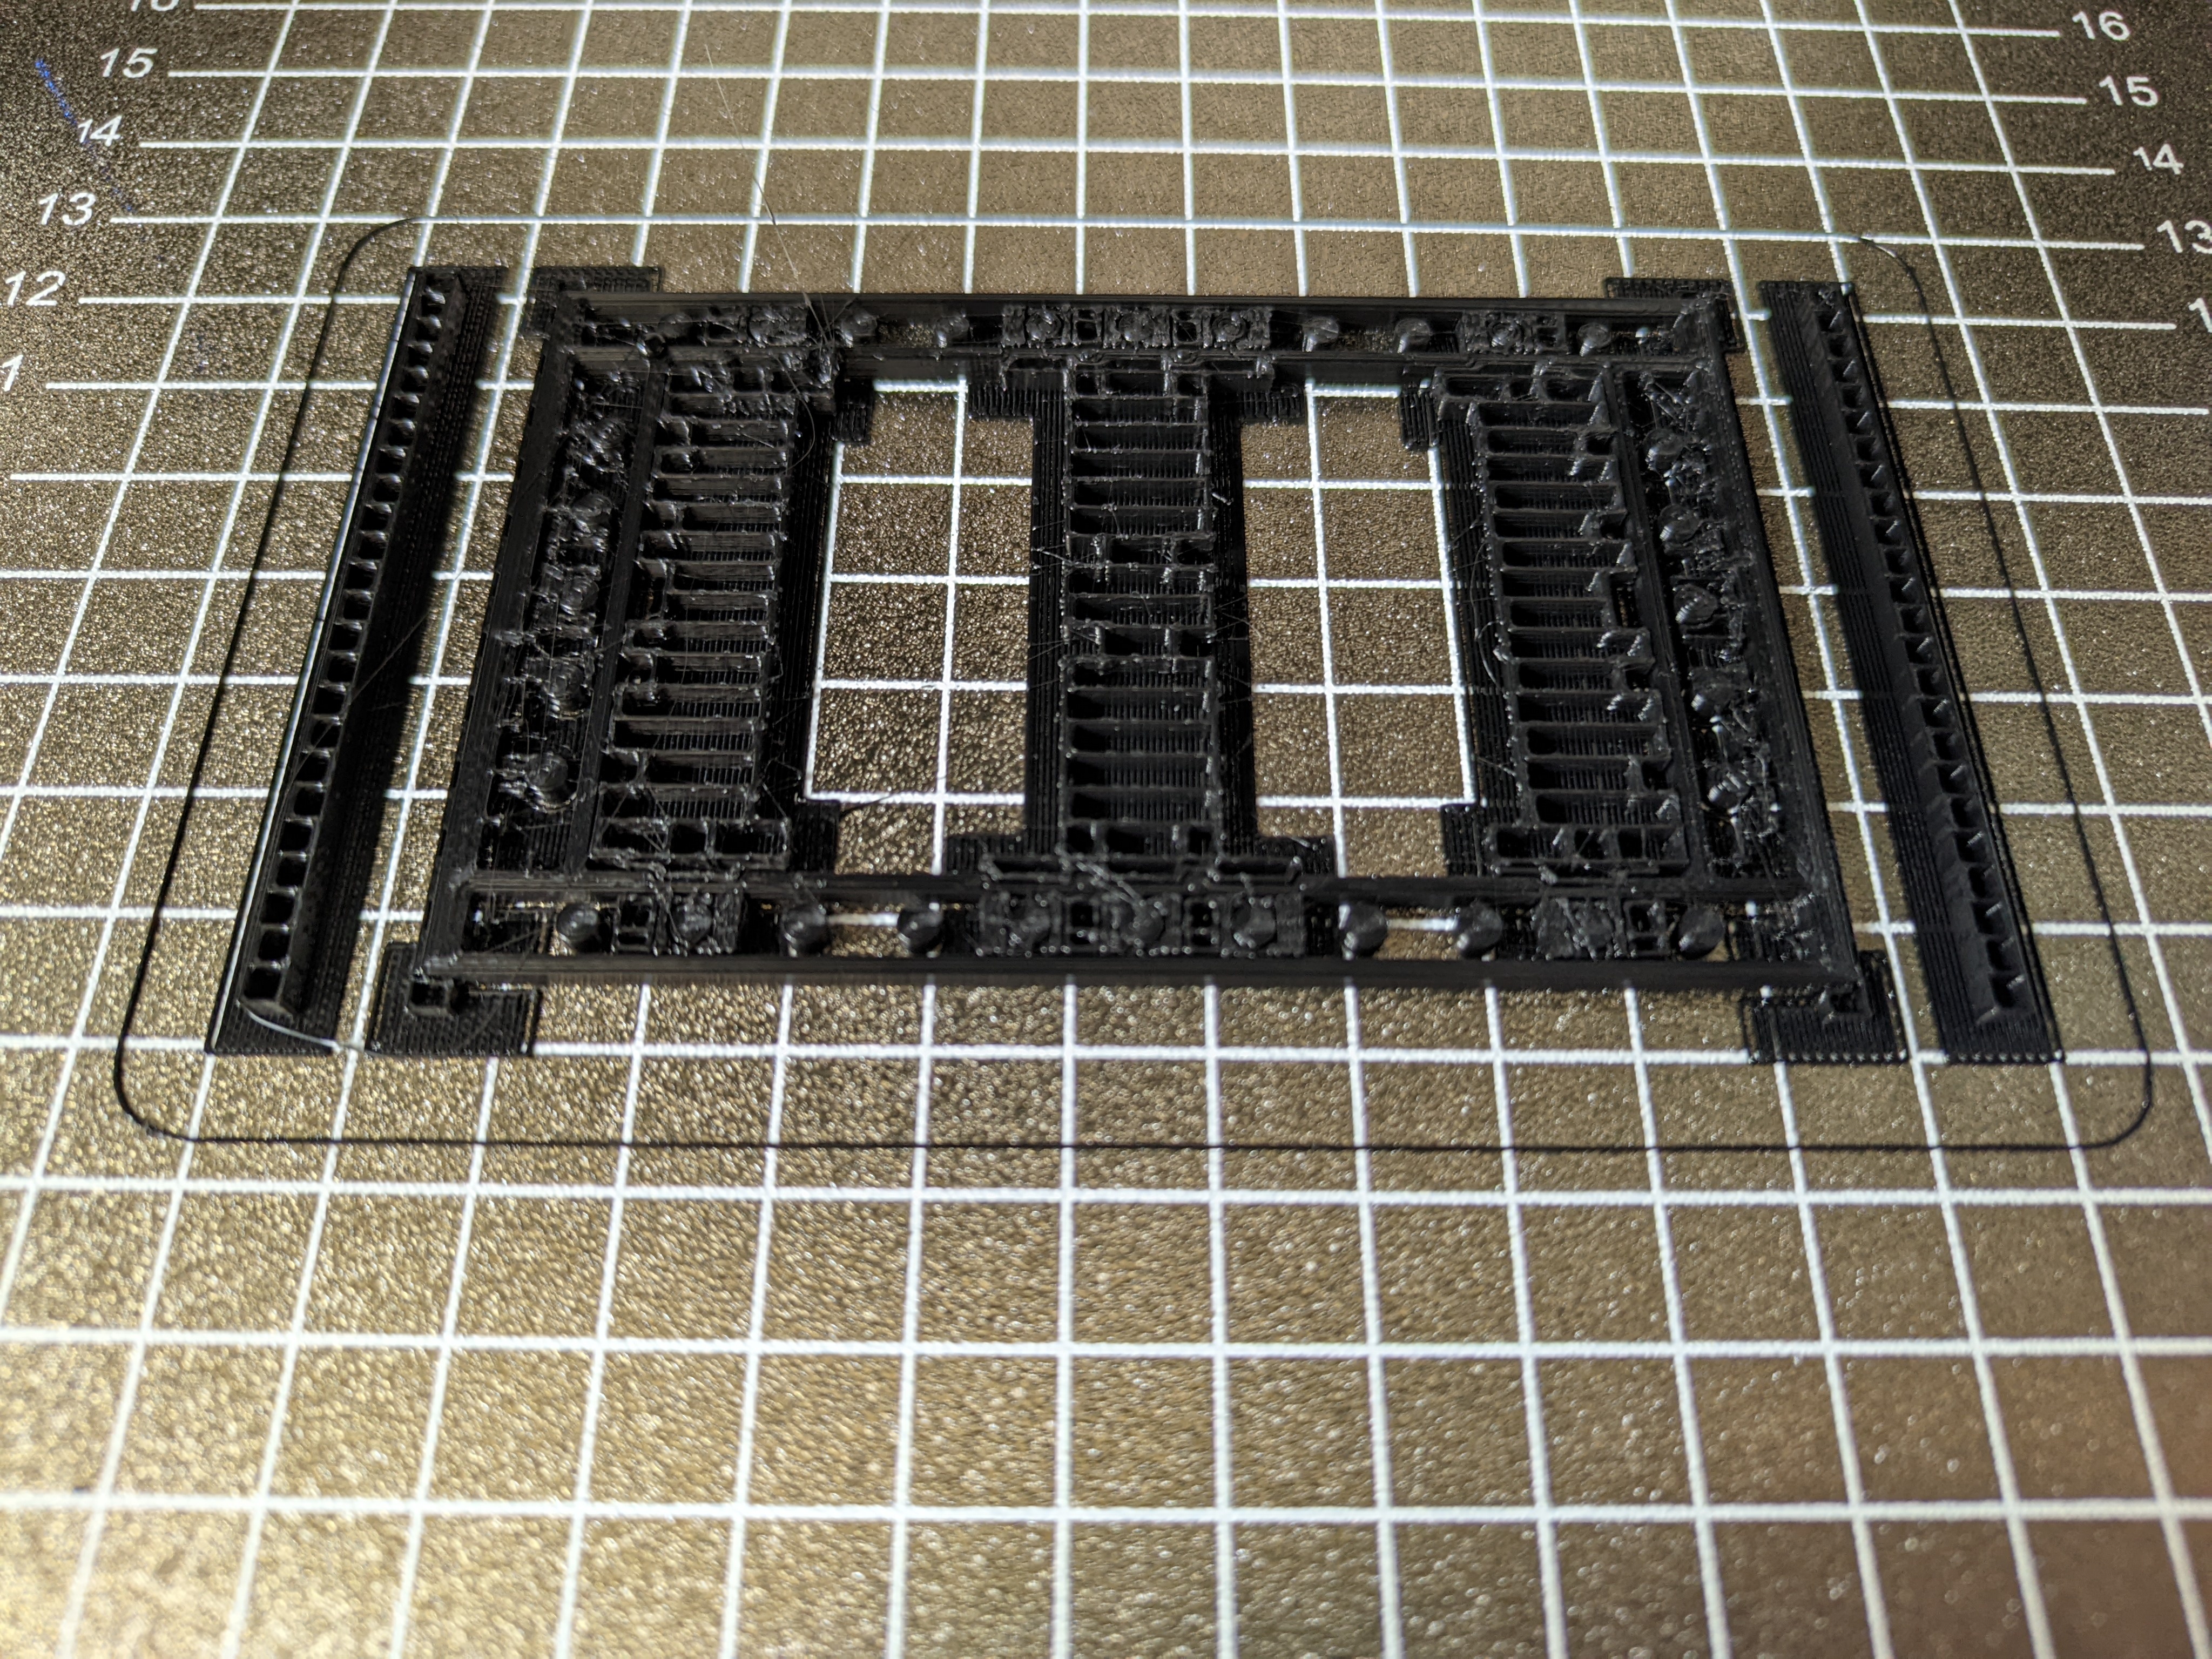
Sovol SV06 stringing issue (discuss.tchncs.de)
submitted 2 years ago* (last edited 2 years ago) by Fisch@discuss.tchncs.de to c/3dprinting@lemmy.world
 

I would really appreciate it if someone could help me with this. I'm having an issue with my Sovol SV06, which is that I get a lot of stringing. I'm still fairly new to 3D printing, so I have no idea what could cause this and how I could go about fixing this. I already searched for this issue online btw but didn't really find anything helpful.

The only change I made to this printer is that I hooked up a Raspberry Pi 4 to it and installed Klipper and Octoprint. I'm also using PrusaSlicer with the config from here.

Edit: Forgot to mention I was using PLA for this print


I'm trying to extract the frames of a video as individual images but it's really slow, except when I'm using jpeg. The obvious issue with jpegs is the data loss from the compression, I want the images to be lossless. Extracting them as jpegs manages about 50-70 fps but as pngs it's only 4 fps and it seems to continue getting slower, after 1 minute of the 11 minute video it's only 3.5 fps.

I suspect it's because I'm doing this on an external 5tb hard drive, connected over USB 3.0 and the write speed can't keep up. So my idea was to use a different image format. I tried lossless jpeg xl and lossless webp but both of them are even slower, only managing to extract at about 0.5 fps or something. I have no idea why that's so slow, the files are a lot smaller than png, so it can't be because of the write speed.

I would appreciate it if anyone could help me with this.


I recently found out that instead of just using online sources, you can also use something you can host yourself, like Komga, in Mihon. I'm just wondering if there's an advantage to it that I didn't think of because the only things I can think of are:

  • Progress is synced over multiple devices
  • Online sources can suddenly go offline, your self-hosted service won't
view more: next ›