
the price of thought
Oh fuck off.
This is a most excellent place for technology news and articles.
the price of thought
Oh fuck off.
These fuckers would sell us air if they could.

I saw it in a documentary called Total Recall

How about DRAM? Show me some AI price crashes leading to DRAM price crashes. That's what we all want, I think.
This still applies.

Surveillance fascism needs the RAM, compute, and storage to implement totalitarianism and autonomous killing machines that won't refuse to genocide the proles once they realize climate change is significantly worse than advertised, and our "democracies" are an illusion controlled by a big club of plutocrats.
When the AI bubble pops, the US government will bail out all the tech companies, and all of the debt will be transferred to the working class via our retirement account losses and inflation; no different to the trillions in "forgiven" corporate loans central banks around the world printed during covid. The working class will essentially pay for the nazi big brother and nazi skynet that enslaves them.
Thanyou for coming to my conspiracy theory ted talk.
I’ve been starting to think that once the bubble begins to pop, the US will bail out the banks by buying up their loans to hyperscalers, and they’ll start writing giant surveillance contracts to AI companies to compensate for the lack of demand. The rich get richer and the resulting stock corrections will end up hurting regular people most
Yeah, whether they buy the excess hardware in a fire-sale, nationalize open AI/Anthropic into the DoD on nat sec grounds, or just sign several hundred billion dollar contracts with them, we're just splitting hairs. The threat and their intentions remain the same.
“Look how low our cost of inference is”
“Pay no attention to the marketing budget that exceeds Coca-Cola’s for a small fraction of their revenues”
What technical, fundamental reason is there for the crash in price? The article just accepts the MSRP as fact. It’s established fact that retail prices can be dropped below cost in order to establish market dominance. The cost of training can indeed be spread over time but it’s not spread across enough time (between model releases)The inference cost doesn’t actually drop in reality.
Let's just quickly check https://isaiprofitable.com/ :
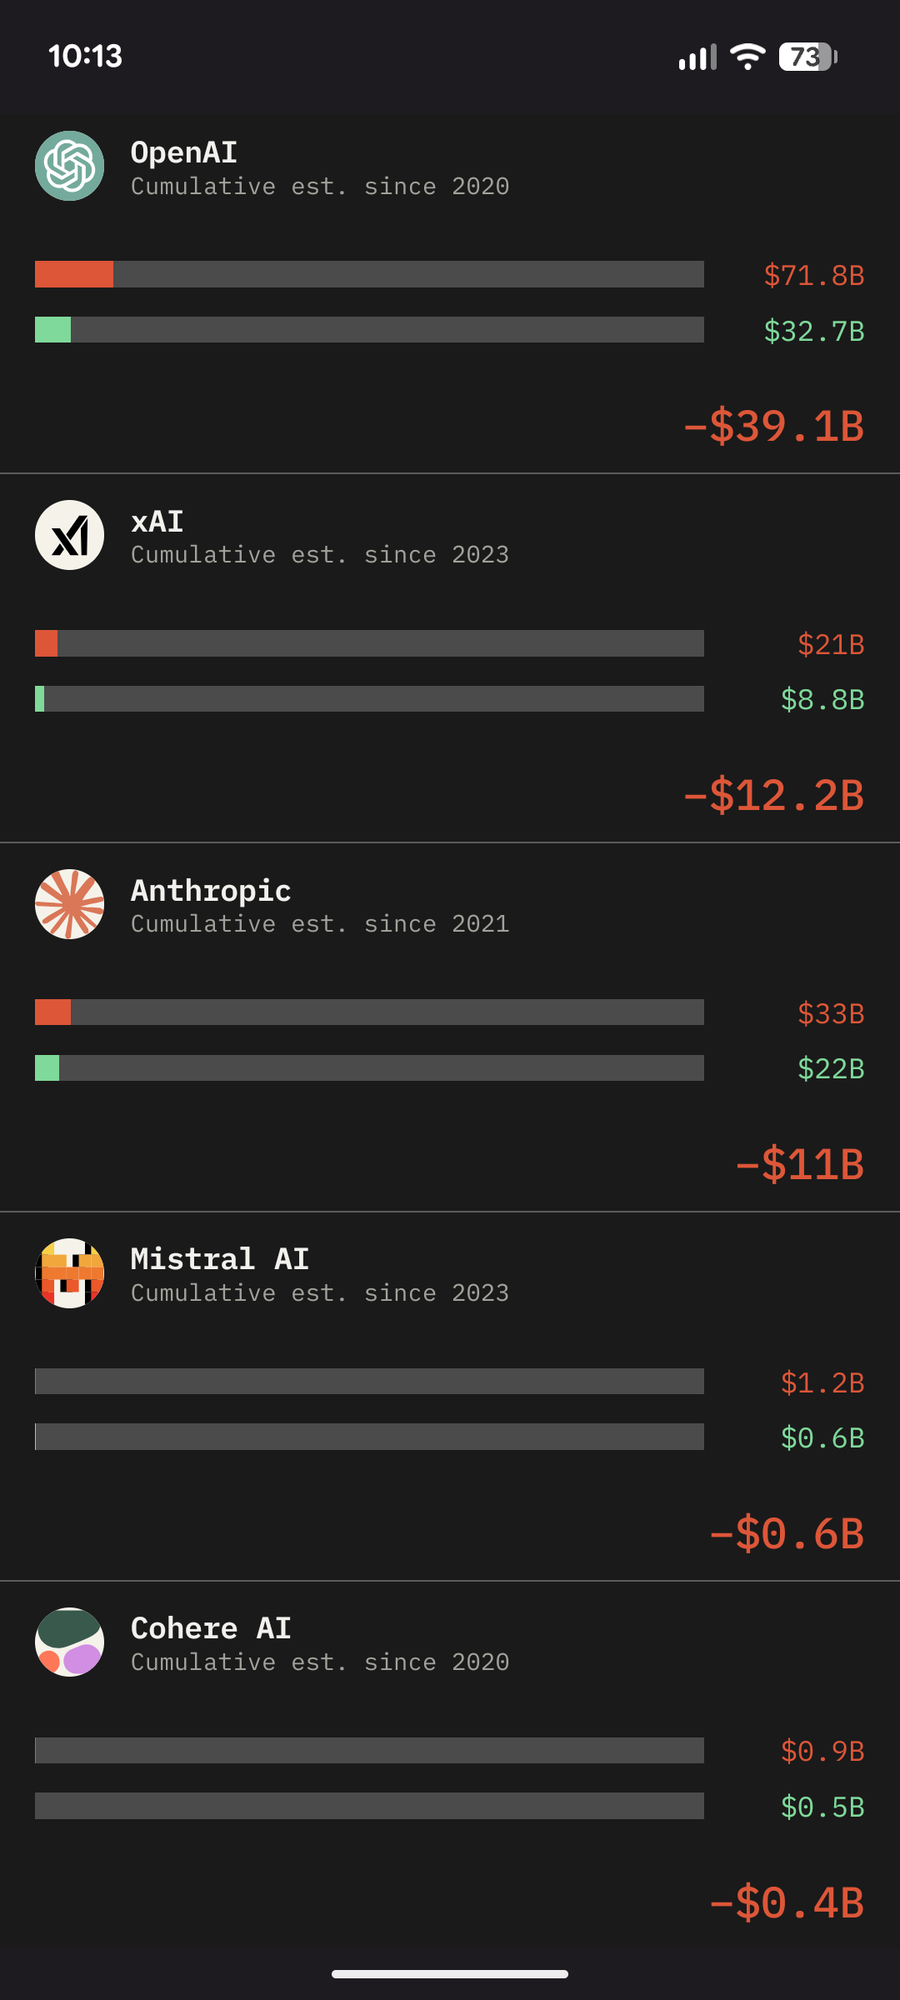
Nope. The answer is still "they're burning cash." Only the companies making silicon are raking it in.
Extremely interesting… so the depreciation of older models is extreme, while new models are constantly presented. And all the while no AI company is making any profit. This whole story is bonkers
The catch is
the cost of a given level of AI performance
And more interestingly the article itself says this
And to this extent, when comparing price drops for AI to drops for other technologies for which we have price series, we are comparing apples and oranges.
Even then, they decided to make it the headline. This is just like LLM bros doing things they don't know anything about. Absolute garbage.
Hadn't you heard? Some day, one of these things is gonna cure cancer. We all just gotta kill ourselves subsidizing it until then!
It's funny watching them rig the system and simultaneously keep shooting themselves in the dick.
Nvidia - desperate not to lose business as they're now ~93% dependent on AI sales, so they keep 'investing' in OpenAI, Anthropic, etc.. Who turn around and of course immediately buy Nvidia AI chipsets.
OpenAI and Anthropic - panicking that investors will realize their IP is worth nothing (what we've said all along) as they are overtaken by much cheaper models, so they lower their pricing drastically - can't risk losing that market share*.
*market share is irrelevant really, there is no first-to-market winner in AI, but you cant lie to ~~idiots~~ investors for another 16 rounds of funding to 2030 unless you can show userbase growth to them.
Really hard to keep propping up the con when barely anyone is paying.
Fingers crossed for horrible things to happen to then soon.
So in essence the price that the market will bare for the cost of AI usage is significantly lower than what the big AI companies would like it to be (in order to pay back their ever growing debts), which means there is a possibility they might never achieve profitability on their own (without some external/governmental strong-arming)
Yeah, I'd like to see the cost of sub-prime mortgage on that chart.
I wonder how they plan to match "prices are in free fall" to "the AI industry will have to make trillions a year in order not to go bust".
On the other hand, "prices in free fall" might be the answer they got from AI...
At this point the cloud model firms are basically banking on making a superinteligence before anyone else and taking over the planet, otherwise they go bankrupt. I wish I was kidding.
Nvidia wins either way though, local models, cloud models, shovels always sell. So they have that overvalued but still realistic bedrock to build houses of cards on.
Nvidia wins unless some other company starts selling cheaper, faster, more efficient matrix multiplication machines.
I've read some articles about radically different inference architectures that may tilt the scales, but I know this is wishful thinking because I really would like Nvidia to fail badly.
Linus_nvidia.gif
That's cool and all, but when can I buy RAM again?
In 4 years or never. The latter probably being the most likely, since they are not just keeping RAM from you for AI purposes. They don't want you to own you own hardware anymore, so they just simply stop manufacturing consumergrade hardware.
Probably not never - CXMT are trying to aggressively expand to fill the market now the major players have left, but it will still be a few years before prices really come down as a result.
Never if you are in the US. In a few years if you are allowed to buy Chinese.
Because those other technologies are infinitely more useful.... So obviously governments and private equity you're going to invest in AI. Makes perfect sense to me.
God I'm so tired
No one knows how useful AI will be in the long term and anyone thinking they know is full of themselves Everyone's gambling.
Like the dotcom bubble, the technology will likely stay long term but the hype scam has been the major issue
It will have some uses. But it will not be the foundation of everything in future tech like they are claiming. It will be some limited mainstay markets, which doesn't in any way justify the size of the hyperscaling they are trying to achieve. All that is pure posturing for the stock value.
Especially since the open source models may likely win out over the big expensive corpo models, based purely on costs.
So what about 5 years? Forget the LLMs, seemingly alot of positive things are happening in various industries thanks to advancements in AI (machine learning, robotics, etc). What about 10 years? What about 25? This is one of those things that will keep advancing, just like computers themselves.
640K ought to be enough for anybody
It's hilarious how many downvotes are given to an objectively true statement. People hate when echo chambers don't confirm their biases.
The other day I saw a video talking about this new innovation on LLM inference side of things where they keep some more used weights in RAM and others less used on disk. I always suspected from the sample code I stumbled upon on the IA world that should be extreme opportunities for optimizations. But I cannot stress it enough how dumb the LLM world is where the basics of implementing an LRU cache is pass of as some big innovation. Like any half competent comp-sci or comp-eng professional know about the basics of mitigating this basics bottlenecks like "the data does not fit on available RAM", "The disk is slow", etc.
So is not surprising that now that it seems that the "powerfulness" of this LLMs is starting to plateau that we would start to see some improvement in performance/resource utilization and hence running costs.
That works for "Mixture of Experts" models. These are basically models with distinct sets of weights and only a subset of them will be used on any particular query. The rest can sit on a disk.
It doesn't work for dense models, where every weight is used all the time. There's nothing inactive so a cache has nothing to exploit.
Keep in mind many of the optimizations you're talking about (LRU caching of experts, for example) are only really relevant at the single user local inference scale. As in, an individual wants to run a big model on their machine, but they don't have enough VRAM to fit the model and KV cache. Accordingly, you're basically only describing hobbyist and research projects, which aren't really representative of the AI inference industry as a whole.
Commercial inference keeps everything resident in VRAM, so expert caching isn't necessary. So these things won't help costs. A lot of other low hanging fruit (like hierarchical KV cache) has also existed for a long time for production-ready inference engines.
Kinda sus that the cost of electricity stops at 1973.
So also less revenue for the AI companies?
Yes, tiny as it is already.
So instead of 1$ return for 3$ spent it's now 4$ or 5$ spent.
So revenue is falling. The only way the bubble grows is forcing this shit into even more places?
Yeah. Not a surprise.
everyone has bet on AI getting good enough to fully replace humans fast. CEOs mandated use of AI. The results weren't as great as expected. CEOs started limiting AI use to counter the token cost explosion after employees found out how to waste tokens fast.
At the same time, China's AI development is driven by the party instead of companies. They aren't so much interested in money as they are in the strategic solution to the demographic problem caused by the one-child policy (which worked a bit too well too fast). The companies there plan on making money by providing the compute (they literally have the power and a two digit number of nucular GW under construction right now).
So their models are almost as good as US ones and freely downloadable to run on whatever hardware you want. That naturally limits the longterm-achievable AI token prices to little more than the cost of just providing the raw compute.
US AI companies are also in a cut-throat competition for customers right from the start. That obviously doesn't help to keep prices high. Currently, they all burn money so fast that it's hard for a human mind to comprehend.
None of the US AI companies will survive the next decade if they don't actually are the only one making AI actually able to fully replace human workers. They will all go bankrupt and might take the whole US economy with them.
Nvidia will probably be the real winner if they don't fuck this up somehow (not sure if that is even possible) because they are the ones selling the shovels in this gold rush.
In two decades, it will be normal to have the capabilities of current frontier models running locally on your Chinese phone.
Moore's Law hasn't been applicable for years.
Yeah gimme some more of that 14nm++++++
All that R&D, and they need to squeeze efficiency out more at this stage. Faster and more specialized is better than big chingus do everything, and means we can hopefully stop spending all that money on making more datacenters.
Personally, I don't use the big chingus models at all... I much prefer local gen if I use it for things. Much better privacy that way, and I'm not throwing money at these jokers.
That's cause you burnt money equivalent of gdp of Spain in that time frame, and I am being generous here.
Yeah, OpenAI released Astra just a couple of weeks ago, then around last week they released Sol 6, which is around half the price of Astra. So you have around the same level of “reasoning” at half the price. They will never turn a profit, at least for the next several years or so.
The cost decline for a given level of performance does tend to slow over time
Even in their tests, there are big drops in 2026 models, and recent ones.
Opus 4.8 (may 2026), by far best model at the time, gets equaled by deepseek 4 pro (july 31) and 4.1 flash (sept 10th) at less than 1/100th the cost. MiMo 2.6 pro (sept 21) is even cheaper and beats opus 4.8 scores by a wide margin. sonnet 4.6 max to gpt luna high is also a 99% cost drop in a short time for lower performance level models.